NeurIPS 2026
Learning to Read Out
Unembedding Dynamics in Language Model Pretraining
1University of Cambridge · 2Flower Labs · 3Isomorphic Labs
A model's hidden states can encode task information before its own readout expresses it.
Abstract
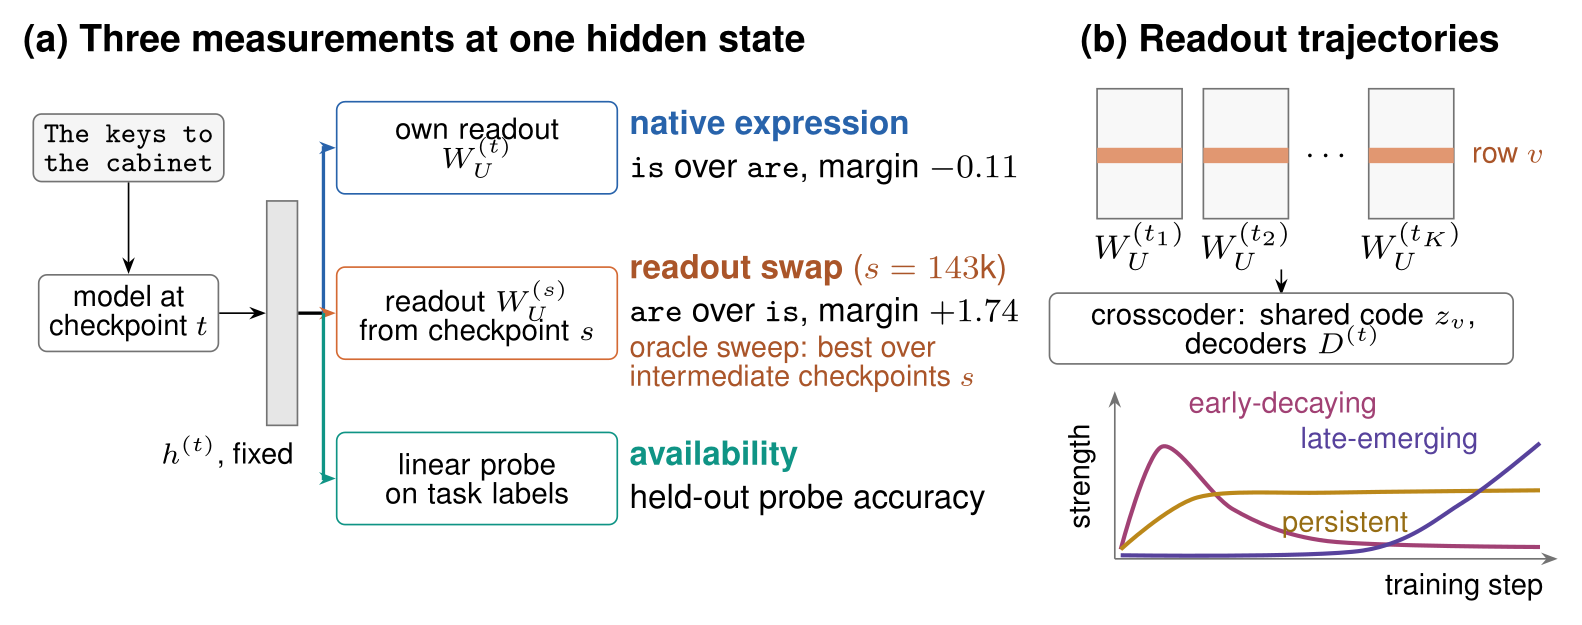
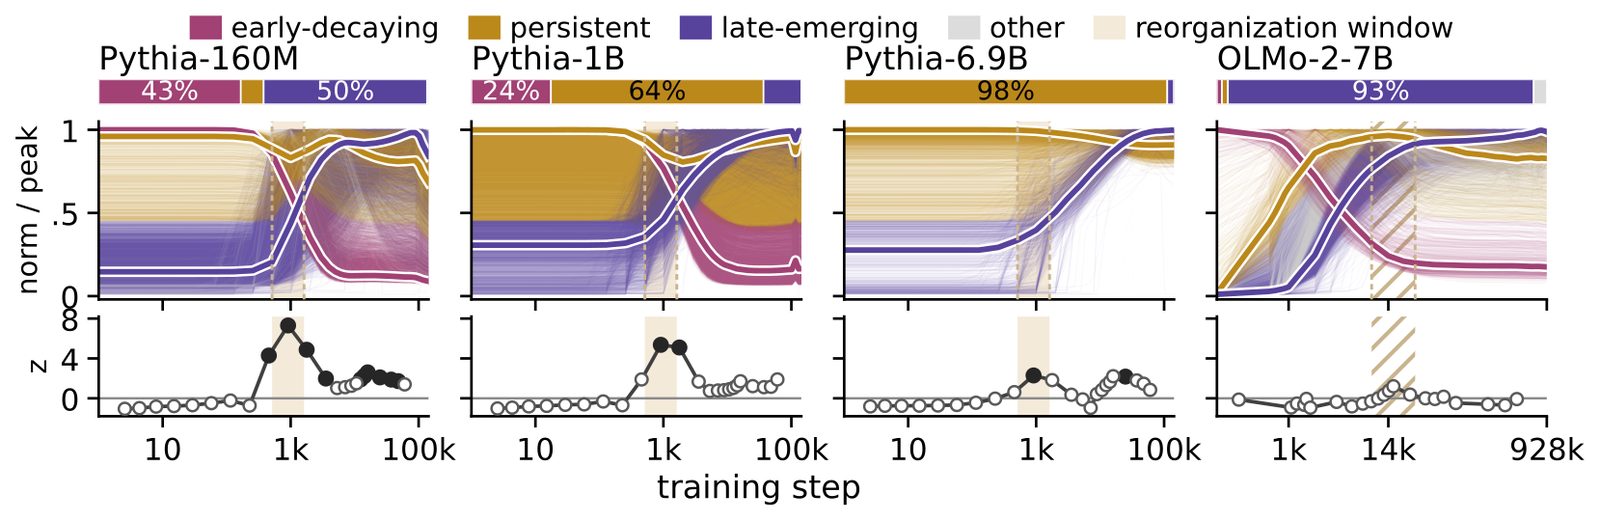
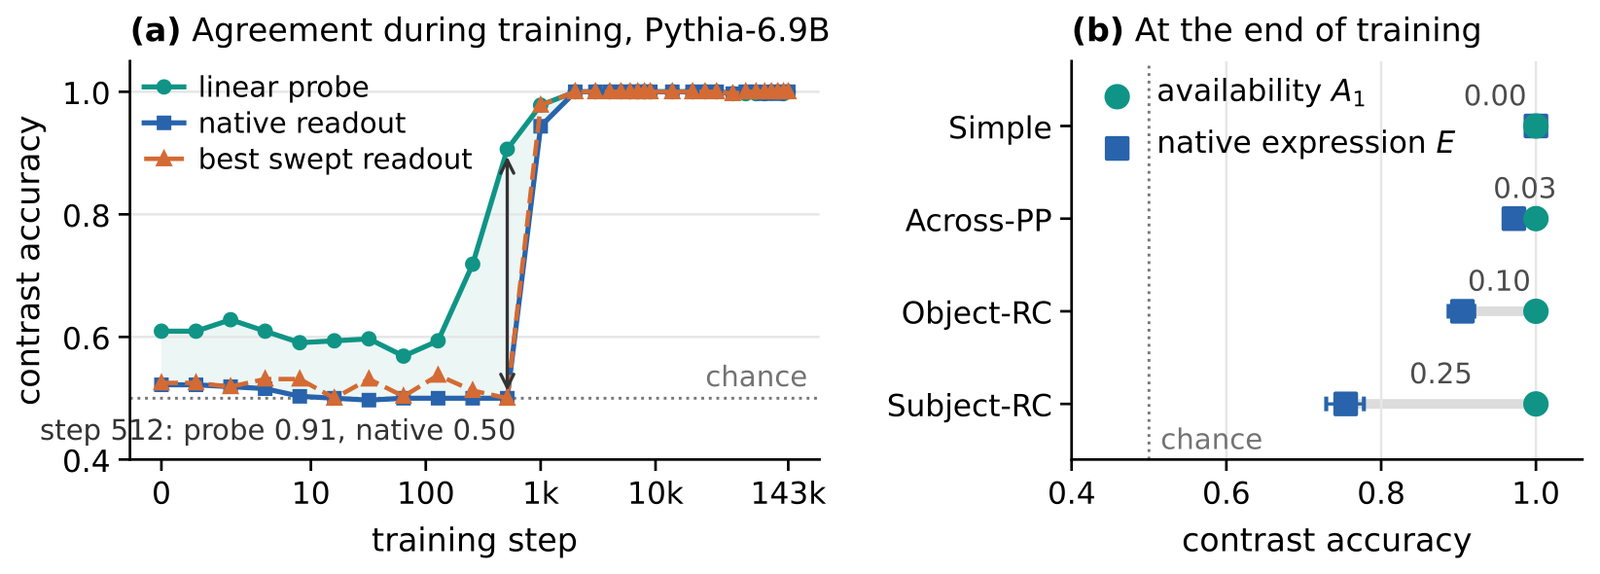
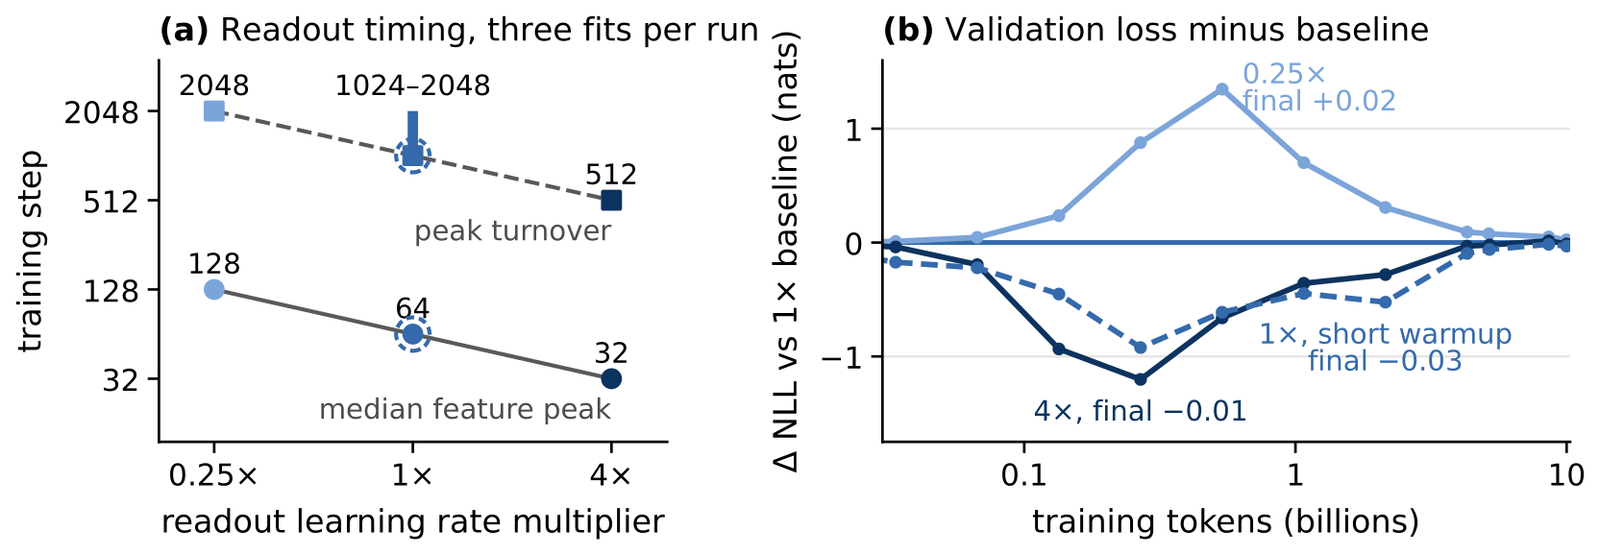
When does a language model acquire a capability? Developmental studies usually answer this by tracking when models start producing the correct token. But that prediction passes through the unembedding matrix, or readout, which is itself still being learned during pretraining. We show that a model's hidden states can encode task information before its own readout expresses it, so timelines read from outputs conflate what the model encodes with what its readout expresses. To track the readout directly, we introduce parameter-trajectory crosscoding, which fits one sparse dictionary to every token's readout row at every checkpoint. Unlike crosscoders on activations, it needs only checkpoint weights. We use it to locate a narrow early window, 0.4–1.1% of the way through Pythia's pretraining, in which the readout reorganizes and WordNet word categories become decodable from its rows. By then, linear probes on the hidden states already decode task information that the model's own outputs do not yet show. To test whether such gaps depend on how fast the readout learns, we pretrain small models from scratch that differ only in the readout's learning rate. We find that raising it makes the readout develop earlier and the gap close sooner, with little effect on final loss. Together, these results imply that early in training, where many developmental transitions are dated, a behavioral date can reflect when the readout learns to express task information and not when the model learns it.
Key results
The readout reorganizes in one early window
Hidden states encode subject number before the readout expresses it
A faster readout develops earlier
Feature atlas
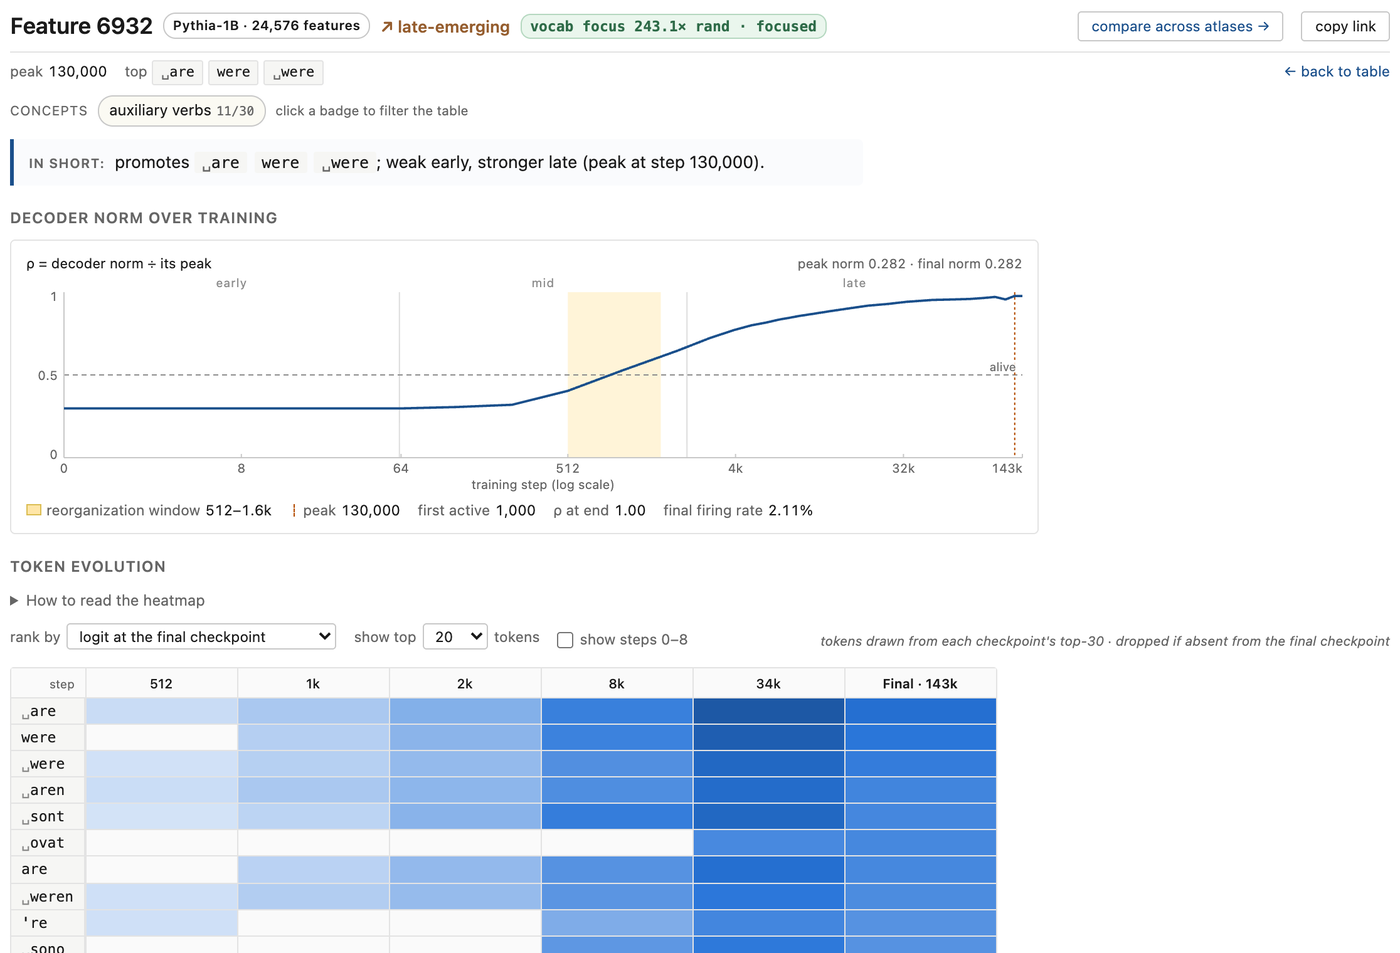
Browse every feature of the readout dictionaries for Pythia-160M, 1B and 6.9B.
- Decoder-norm trajectory over 32 checkpoints, with the reorganization window
- Top tokens at checkpoints across training
- Lifecycle profiles, concept labels and matches across model sizes
Use the dictionaries
List the tokens that one feature promotes at the final checkpoint. This example downloads the 1.6 GB Pythia-160M dictionary; all dictionaries are on Hugging Face, and the code reproduces the paper.
# pip install huggingface_hub safetensors torch transformers
from huggingface_hub import hf_hub_download
from safetensors import safe_open
from transformers import AutoTokenizer

# Pythia-160M readout dictionary: 8,192 features fitted across 32 checkpoints.
path = hf_hub_download("hematteo/parameter-trajectory-crosscoders",
                       "pythia-160m/W_U/cross-snapshot-32/d8192/seed0.safetensors")
with safe_open(path, "pt") as f:
    W_D = f.get_slice("W_D")[31:32][0].float()  # decoders at the final checkpoint, (8192, 768)

# The model's own readout (unembedding) at the same checkpoint.
weights = hf_hub_download("EleutherAI/pythia-160m", "model.safetensors")
with safe_open(weights, "pt") as f:
    W_U = f.get_tensor("embed_out.weight").float()  # (50304, 768)
tok = AutoTokenizer.from_pretrained("EleutherAI/pythia-160m")

feature = 7518
top = (W_U @ W_D[feature]).topk(8).indices
print([tok.decode(i) for i in top])
# [' food', ' eat', ' meal', ' eating', ' nutrition', ' diet', ' meals', 'food']
Related
Sparse Readout Prism: Explaining Logit-Lens Scores in Features Instead of Tokens (code).
BibTeX
@inproceedings{he2026learningtoreadout,
  title     = {Learning to Read Out: Unembedding Dynamics in Language Model Pretraining},
  author    = {He, Matteo and Shen, William F. and Iacob, Alex and Jovanovic, Andrej and Qiu, Xinchi and Lane, Nicholas D.},
  booktitle = {Advances in Neural Information Processing Systems},
  year      = {2026},
  eprint    = {2610.21025},
  archivePrefix = {arXiv},
  primaryClass  = {cs.CL}
}